The Diamond Data Normalisation Problem: Reconciling Feed Schema for Google’s Knowledge Graph
Modern diamond e-commerce platforms are built on data feeds.
Retailers import inventory from suppliers such as Nivoda, RapNet, Virtual Diamond Boutique, and other B2B diamond marketplaces. Within minutes, thousands—or even hundreds of thousands—of stones appear inside a catalogue.
Operationally, this is a remarkable convenience.
Architecturally, however, it creates a hidden problem that very few retailers recognise until their search visibility begins to degrade.
The problem is data normalisation.
More specifically, it is the inability of most diamond stores to reconcile conflicting supplier vocabulary into a single canonical product model that search engines can reliably interpret.
The consequence is subtle but severe: fragmented attributes, unstable structured data, and inconsistent product entities that fail to align with Google’s Knowledge Graph.
Understanding and solving this issue is central to building a scalable diamond e-commerce architecture.
The Hidden Vocabulary Crisis in Diamond Feeds
Most diamond retailers assume that the primary challenge of feed integrations is inventory ingestion.
They worry about:
- importing diamonds from suppliers
- updating prices and availability
- synchronising inventory in real time
These are operational concerns.
The real architectural challenge lies elsewhere.
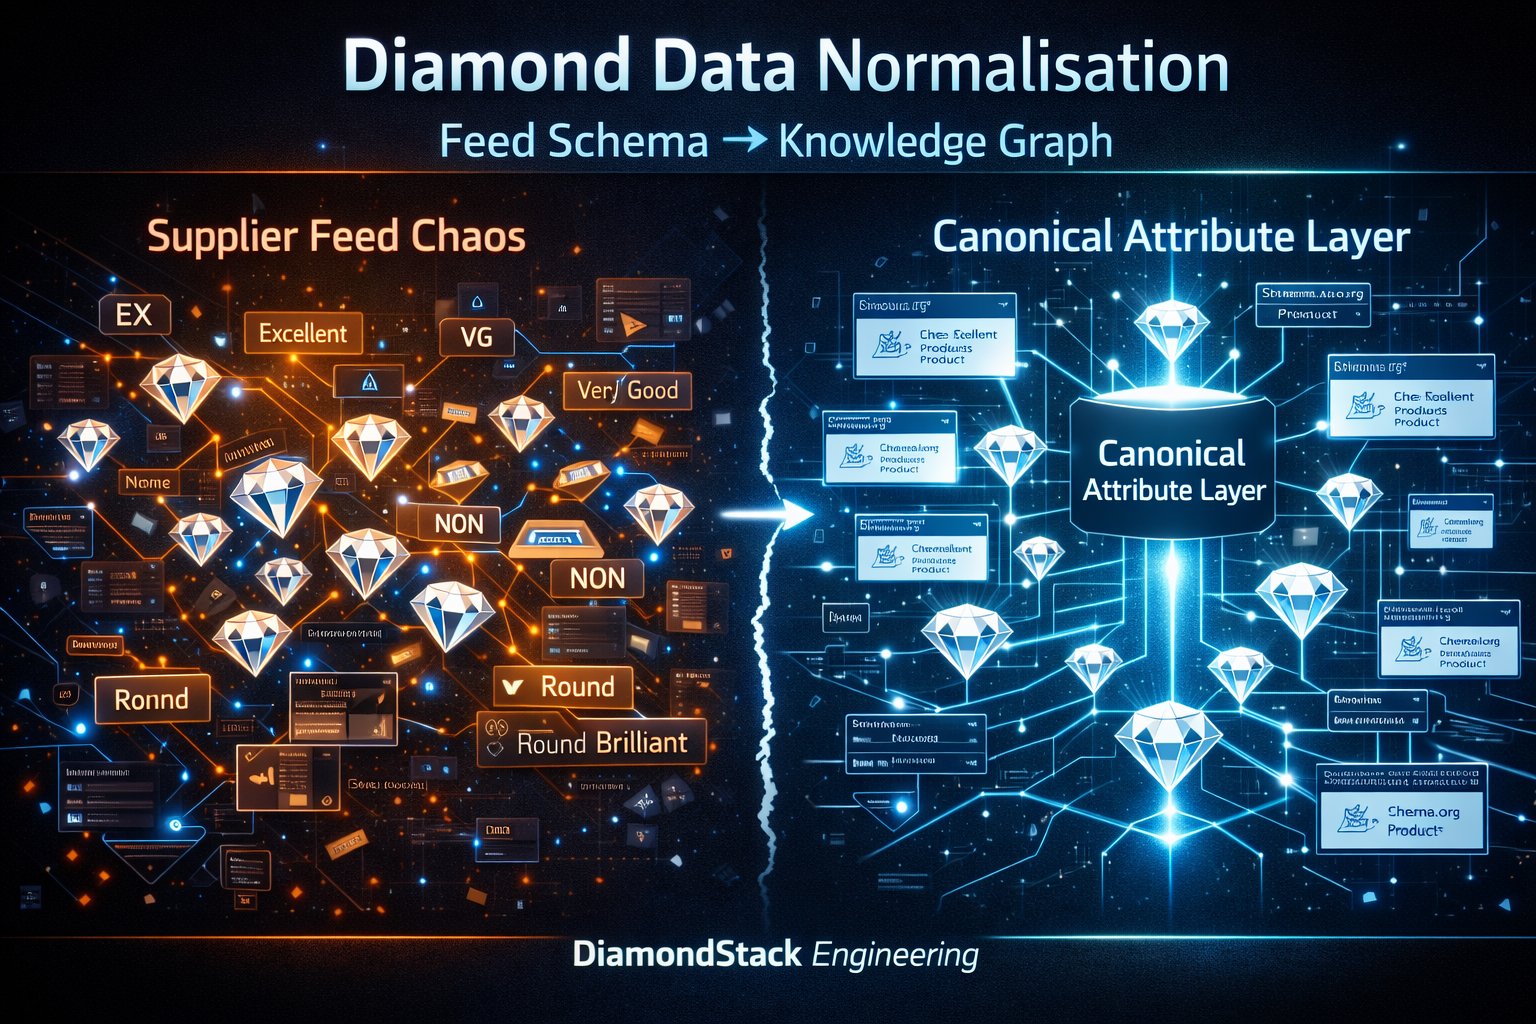
Supplier feeds describe the same diamond attributes in different semantic formats. When these conflicting descriptions are merged directly into a store’s catalogue, the result is a fragmented attribute layer.
Instead of a clean product vocabulary, the store accumulates multiple competing representations of the same attribute.
For search engines attempting to understand product entities, this inconsistency creates ambiguity.
Why Supplier Feeds Disagree
Different suppliers use different attribute standards.
Some use human-readable values. Others use abbreviations designed for database efficiency.
For example:
| Attribute | Supplier A | Supplier B |
|---|---|---|
| Cut | Excellent | EX |
| Cut | Very Good | VG |
| Fluorescence | None | NON |
| Shape | Round Brilliant | Round |
| Certification | GIA Certified | GIA |
Each representation technically describes the same fact.
But machines do not interpret them as equivalent unless the system explicitly maps them together.
Without normalisation, the catalogue may contain multiple variations of what should be a single attribute.
The SEO Cost of Attribute Fragmentation
Inconsistent attribute values produce cascading SEO problems across the site’s architecture.
Structured Data Instability
When structured data is generated from inconsistent attributes, Schema.org markup becomes fragmented.
Two identical diamonds might produce structured data like:
"cut": "Excellent"
and
"cut": "EX"
To a machine interpreting structured data, these values are not necessarily equivalent.
This weakens entity resolution and reduces the reliability of product signals.
Filter Fragmentation
Faceted navigation depends on consistent attribute values.
If the same attribute appears under multiple variations, filters become inconsistent.
Examples include:
- Excellent vs EX
- None vs NON
- Very Good vs VG
The result is duplicate filter paths and fragmented navigation structures.
URL Instability
Attribute fragmentation also creates inconsistent URLs in faceted navigation.
Instead of a single filter path, the site generates multiple variations:
/diamonds?cut=excellent
/diamonds?cut=ex
Each path represents the same attribute but creates separate crawlable URLs.
Over time, this generates crawl inefficiencies and dilutes ranking signals.
Product Entity Ambiguity
Search engines increasingly rely on entity understanding to interpret products.
If product attributes are inconsistent, the system cannot reliably cluster similar diamonds into coherent entity groups.
This weakens the store’s alignment with Google’s Knowledge Graph.
Why Google Needs a Canonical Vocabulary
Search engines prefer structured, predictable product vocabularies.
A well-structured catalogue uses consistent attribute values that map cleanly into machine-readable schema.
For example:
Cut: Excellent
Colour: G
Clarity: VS1
When these attributes are consistently defined, Google can confidently interpret the product entity.
But when attributes appear as:
Cut: Excellent
Cut: EX
Cut: EXC
the system must guess whether these values represent the same concept.
Ambiguity forces search engines to rely on probabilistic inference instead of deterministic understanding.
That uncertainty reduces the strength of product signals.
Feed-Agnostic Attribute Mapping
The solution is to create a canonical attribute layer independent of any supplier feed.
Instead of allowing supplier terminology to dictate the store’s vocabulary, the platform establishes its own internal attribute dictionary.
Every supplier value is then mapped into this canonical structure.
A typical mapping structure might include:
| Supplier Value | Canonical Internal Value | Display Value | Schema Output |
|---|---|---|---|
| EX | excellent | Excellent | Excellent |
| Excellent | excellent | Excellent | Excellent |
| VG | very_good | Very Good | Very Good |
This approach ensures that regardless of how upstream suppliers label a diamond, the store always resolves the attribute to a stable internal representation.
Attribute Certainty in the Coetzee Liquidity Protocol
This principle is formalised within the Coetzee Liquidity Protocol (CLP).
CLP introduces the concept of Attribute Certainty (Ui).
Attribute Certainty states that every product attribute must resolve to a single, unambiguous machine meaning regardless of how upstream data sources label it.
Under this model:
- supplier vocabulary becomes input data
- canonical attributes become system truth
This separation allows the platform to maintain semantic consistency even when integrating multiple feeds.
Attribute Certainty improves:
- structured data stability
- entity resolution
- canonical product modelling
- faceted navigation logic
- cross-platform data portability
Without this certainty layer, the entire product architecture remains dependent on supplier dialects.
Normalisation Architecture for Diamond Retailers
A robust diamond data architecture typically includes several layers.
Feed Ingestion Layer
Supplier APIs are ingested into a staging database without altering the raw data.
This preserves the original supplier values for auditing and reconciliation.
Mapping Rules Engine
A rules engine converts supplier values into canonical attributes.
For example:
EX → excellent
VG → very_good
NON → none
These mappings standardise the vocabulary used throughout the platform.
Canonical Attribute Store
Normalised attributes are stored in a central attribute dictionary.
This dictionary becomes the single source of truth for:
- filters
- structured data
- search indexing
- product display
Validation Layer
Incoming feed values are validated against the canonical dictionary.
If an unknown attribute appears, it is flagged for review before entering the system.
This prevents new supplier variations from silently fragmenting the catalogue.
Schema Output Layer
Once attributes are normalised, structured data can be generated consistently.
Product schema now outputs stable values such as:
"cut": "Excellent"
"color": "G"
"clarity": "VS1"
This improves search engine understanding and strengthens entity recognition.
Schema.org/Product and the Diamond Data Layer
When attributes are normalised, the product data layer becomes far more powerful.
The canonical attribute model can drive:
- Schema.org Product markup
- Google Merchant feeds
- internal faceted navigation
- landing page generation
- internal search indexing
Because every attribute resolves to a deterministic value, the system produces consistent structured data across all channels.
This alignment dramatically improves Knowledge Graph compatibility.
Shopify vs WooCommerce Implications
Different platforms handle attribute normalisation differently.
Shopify
Shopify’s architecture relies heavily on metafields and app-based integrations.
Without a dedicated mapping layer, supplier attribute inconsistencies easily propagate throughout the catalogue.
This can result in fragmented filters and unstable structured data.
WooCommerce
WooCommerce offers deeper database control, making it easier to implement canonical attribute dictionaries.
Custom taxonomies and mapping tables allow developers to enforce attribute normalisation before values appear in the product layer.
For large diamond catalogues, this flexibility often makes WooCommerce better suited to advanced data modelling.
When Normalisation Becomes Mandatory
Many small retailers initially ignore feed normalisation.
But as catalogue complexity grows, the absence of a canonical attribute layer becomes unsustainable.
Normalisation becomes essential when:
- multiple supplier feeds are integrated
- inventory exceeds 5,000 stones
- the store targets international search traffic
- structured data drives merchandising strategy
- AI search visibility becomes a priority
At this scale, relying on supplier vocabulary creates too much semantic instability.
Strategic Conclusion
Diamond retailers often believe their competitive advantage lies in access to inventory.
In reality, the advantage increasingly lies in data architecture.
Suppliers provide diamonds, but they do not provide semantic consistency.
Retailers who simply import feeds inherit supplier vocabulary chaos.
Those who implement a canonical attribute layer gain something far more valuable: a stable product model aligned with search engines and machine understanding.
As search systems become increasingly entity-driven, the stores that control their attribute vocabulary will control their discoverability.
Feed ingestion may populate a catalogue.
But only data normalisation creates a product architecture that search engines truly understand.